Law, Ethics & Technology
ISSN: 2959-3077 (Print)
ISSN: 2959-3085 (Online)
CODEN: LETAA8
CiteScore 2025: 1.3
Digital cultural heritage under EU copyright influence in two Black Sea States
This article examines how national legal structures affect the reception of the European Union framework for digital preservation and public-domain access outside the Union. Articles 6, 7 and 14 of Directive 2019/790 provide the benchmark. They address preservation copying by cultural heritage institutions, protection of exceptions against contractual restrictions and their connection with rules on technological protection measures, and the exclusion of new copyright or related rights in non-original reproductions of public-domain visual art. The analysis identifies two regulatory configurations among EU Member States: copyright-centered implementation of the Directive, and copyright implementation operating alongside non-harmonized national public-law controls over cultural heritage reproductions. Ukraine and Türkiye are examined as two ways of responding to EU copyright rules. Ukraine has moved closer to the EU model through copyright reform and participation in European digital cultural heritage initiatives. Its legislation already covers some functions reflected in Articles 6 and 14, but gaps remain. These include contractual override, the use of works for preservation when technological protection measures prevent access, and the status of non-original reproductions of public-domain visual art. Türkiye follows a different approach. Copyright, legal deposit, and cultural heritage rules regulate these issues separately. Electronic legal deposit supports preservation through the National Library, but there is no copyright exception allowing cultural heritage institutions to preserve collections. Administrative permissions and controls also affect the creation and reuse of cultural heritage reproductions. The comparison identifies three modes of functional reception–direct legal transmission, institutional and procedural transmission, and functional convergence–and treats non-transmission as a separate category for EU functions left unperformed. In the cases examined, reception is more complete where copyright permissions, technological safeguards, legal-deposit mechanisms and cultural heritage administration are institutionally coordinated. Equivalent protection for preservation and public-domain access depends on the coordinated legal and institutional effects of the national framework.

Reconstructing consent in genomic AI: SCOT, respect for persons, and the case for dynamic consent
Artificial intelligence (AI)-driven genomic research challenges prevailing consent frameworks by enabling iterative data reuse, cumulative inference, and intergenerational risk that static, one-off consent cannot adequately address. This article applies the Social Construction of Technology (SCOT) and the principle of Respect for Persons (PRP), interpreted through relational autonomy, to examine how regulatory categories such as broad consent, minimal risk, and compatible purpose are socially constructed, institutionally stabilised, and ethically consequential. In this context, consent rules operate not merely as mechanisms of authorisation but as governance tools that allocate responsibility, shape expectations, and determine the legitimacy of downstream data use over time. Through a comparative analysis of the EU General Data Protection Regulation (GDPR) and the U.S. Common Rule (U.S.C.R.), the article demonstrates how categorical exemptions and procedural consent under the U.S.C.R. fail to ensure sustained participant protection in genomic AI, while the GDPR embeds consent within a cumulative legality architecture grounded in Articles 5, 6(4), 9, and 89(1), with Recital 33 guiding interpretation. The article argues that dynamic consent does not constitute an independent lawful basis under the GDPR but may offer a doctrinally compatible and ethically robust governance mechanism capable of operationalising existing GDPR obligations. It may do so by enabling iterative engagement, granular permissions, and accountability across evolving research contexts, particularly in dual-regulation environments such as Qatar, where GDPR-style frameworks coexist with U.S.C.R. requirements.

Anonymization dilemma of generative artificial intelligence and its countermeasures
The development of generative AI relies on large-scale corpora that often contain personal information, making anonymization central to data-protection compliance. In comparative law, anonymization generally determines whether personal-information protection rules apply, with the key inquiry turning on identifiability and the reasonable likelihood of re-identification. In generative AI, however, parameterized learning, dynamic content generation, and long-term interaction have transformed anonymization from a static processing outcome into a probabilistic and context-dependent risk condition. This creates three main challenges: a mismatch between formal anonymization and substantive risk, which may lead to identity disclosure or sensitive-attribute inference; the erosion of anonymization’s function as a regulatory boundary, which may enable regulatory circumvention and undermine public trust; and uncertainty over responsibility allocation, which may hinder risk prevention, enforcement, and remedies. Existing rules offer only limited responses to residual risks, jointly produced risks, and dynamic changes in model operation. Accordingly, anonymization should be reconceptualized as an ongoing governance framework based on context-sensitive identifiability standards, tiered legal consequences, responsibility allocation, and lifecycle oversight, thereby reconciling personal-information protection with AI development.

Artificial integrity: social performativity of honesty in the age of generative AI
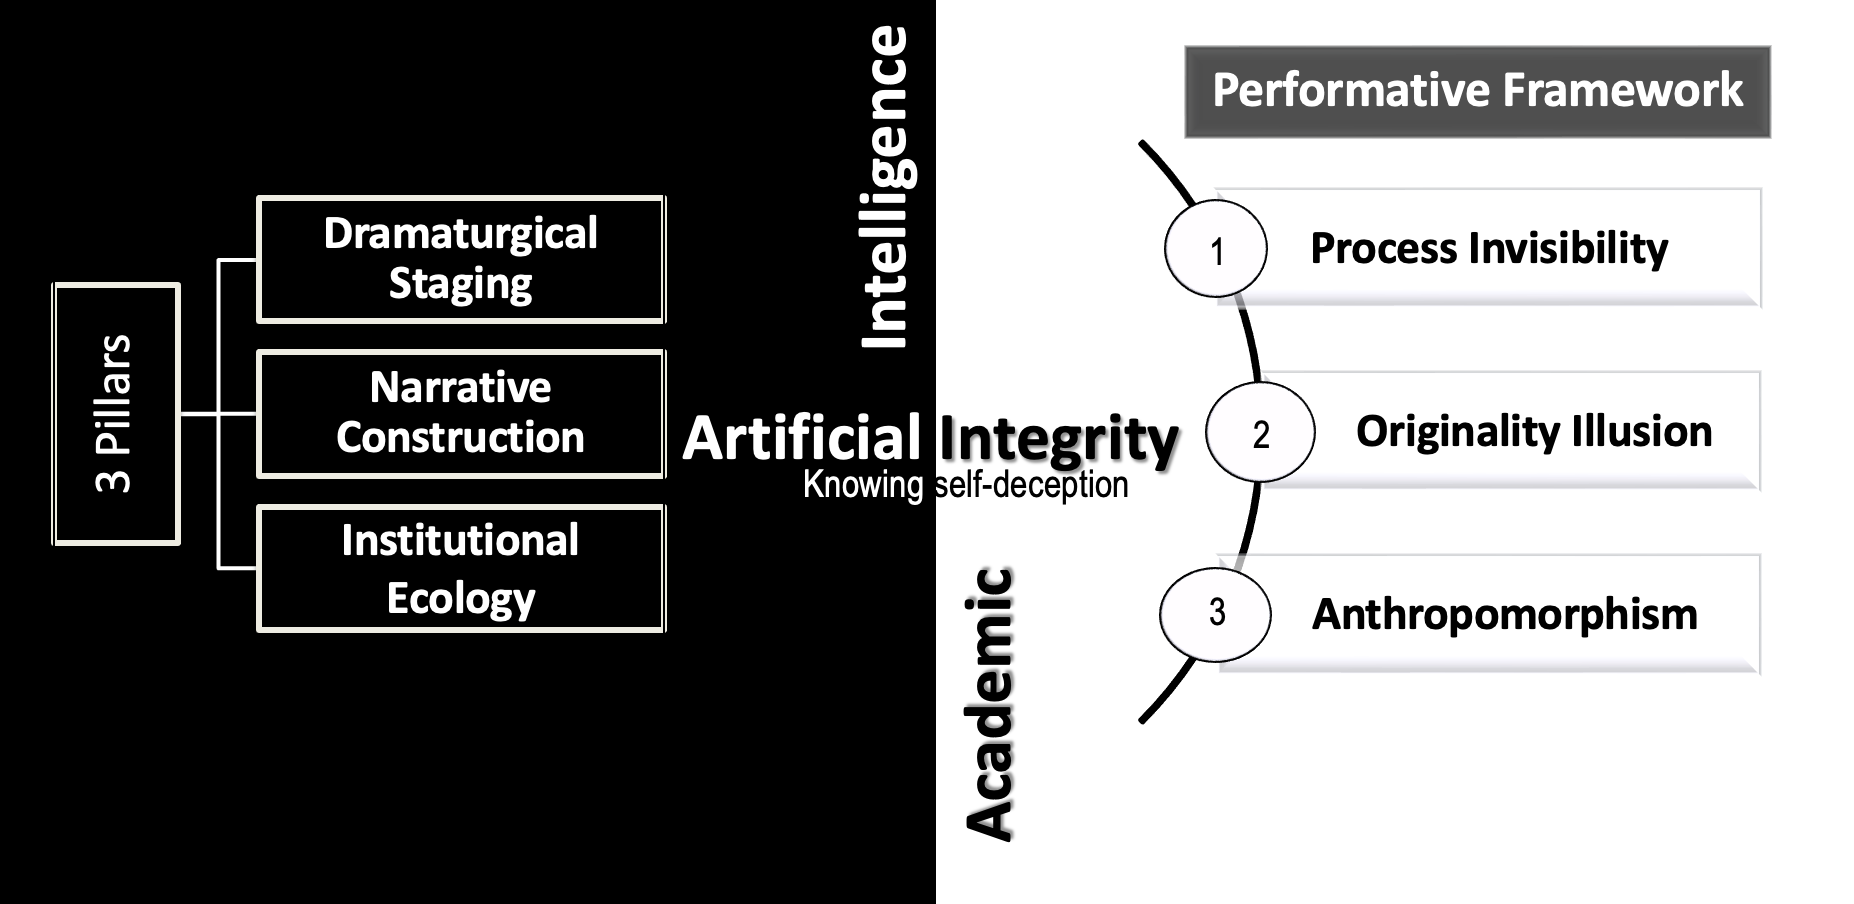
This article analyzes the paradoxical phenomenon in which students extensively utilize generative AI for academic work while sincerely maintaining that their submissions are honest and original. Beyond simple confusion or concealment, it introduces artificial integrity: a techno-ethical dilemma arising from technologically scaffolded knowing self-deception. Drawing from dramaturgical analysis, narrative identity theory, and recent empirical research, a framework is developed that reveals how integrity is socially performed and stabilized within ambiguous institutional ecologies. The analysis demonstrates that students, while retaining awareness of AI’s core intellectual labor, sustain credible honesty claims through epistemic layering, manifesting in strategic disclosure, resistance to transparency, and persistent anxiety. This condition is co-produced by institutional designs that prioritize polished outputs over visible process, creating a rationalization space where traditional legal-ethical frameworks for authorship and accountability break down. Rather than policing AI use, this article argues institutions must develop clear, legally sound AI-use policies and redesign assessment to mandate transparency, through methods such as process portfolios, reflective annotations, and structured disclosure protocols, thereby resetting the academic stage to reward visible cognition over performative authorship.
The integration of blockchain technology with arbitration mechanisms: its efficacy and implementation in international arbitration

From design to decommissioning: TAFES framework for responsible AI
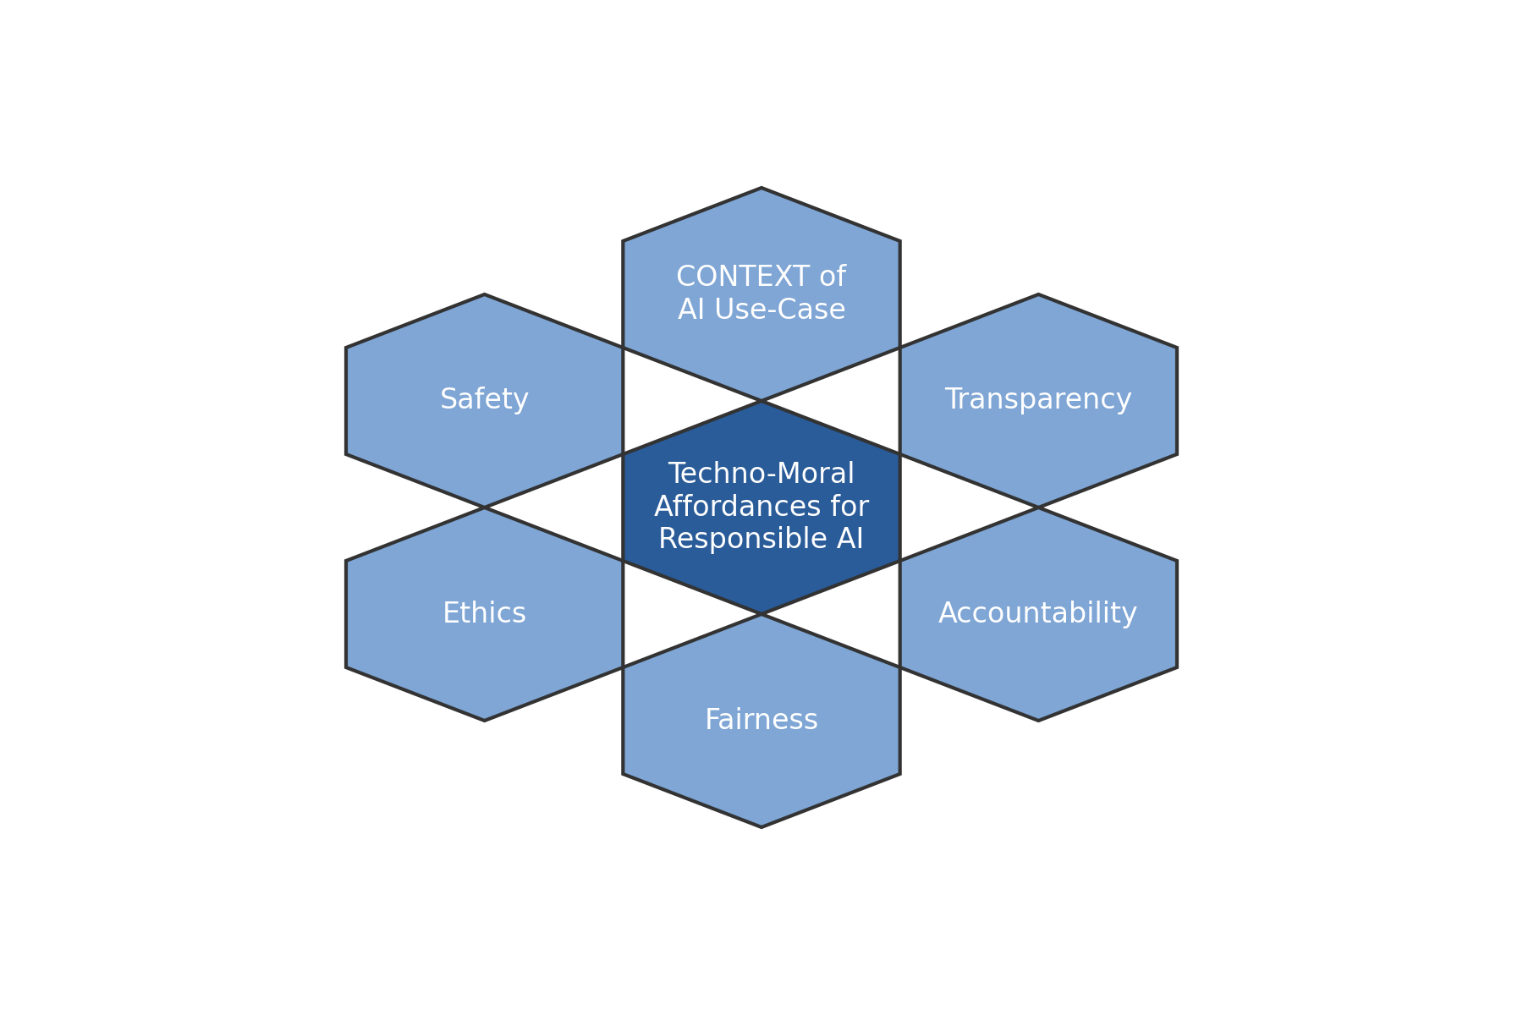
Artificial Intelligence (AI) systems demand comprehensive governance frameworks that ensure ethical, transparent, and accountable practices across their entire lifecycle. This paper presents the TAFES framework—comprising Transparency, Accountability, Fairness, Ethics, and Safety—as a theoretically grounded and practically implementable approach for responsible AI. Through systematic analysis of existing global frameworks and an applied healthcare use case (Nurse Linda), TAFES demonstrates how ethical principles can be operationalized through lifecycle processes spanning design, development, deployment, and decommissioning. Unlike regulatory or risk-centric models such as the NIST AI RMF or EU AI Act, TAFES integrates moral philosophy with engineering implementation to bridge the gap between ethical intent and practical execution.